Showing posts with label tools. Show all posts

2014/02/08

Ultimate hosting solution for static websites


How often do you create simple web pages? No PHP, or anything, just pure HTML+CSS. How ofter do you update them? Do you use version control system for this purpose just like for other dev projects? How about hosting your project directly from the source code repository? Wouldn't that be perfect?

In the previous post I described how to use lftp to effectively update website on FTP server with the trick of reverse mirror mode. But if you are using GIT for versioning your HTML (which I strongly recommend even if there are no other people working on the project), you are also quite likely using GitHub for keeping your source code. Do you know that you can host your website directly from GitHub infrastructure? For free.

Of course it is possible to use custom domain name. In order to fully utilize GitHub's global Content Delivery Network it is advised to use CNAME record with for example www subdomain prefix to canonicalize domain name. Be sure to choose domain registrar which will allow you to configure HTTP 301 redirection for the main domain.

2011/04/02

2011/01/31

Tadedon - solid ground for any Java application

Some time ago I started project called tadedon. The name is coined by my little son Alan (Polish), and I assume it is short, unique, and easy to remember.

The whole projects consists of several maven modules, which are intended to be flexible tools for solving common problems. Each module is built on top of library like Guice, GWT, commons-configuration, etc. Tadedon modules shouldn't be considered as extensions to these libraries, but rather as a thin layer of code which allows to use these libraries in special contexts. Here is an example of tadedon-guice-servlet-mock module which supports unit testing of Guice Servlet Modules without the need of real servlet container.

I have already released version 1.0. Now tadedon needs some attention - it should attract more users, and developers. Any contributions are welcome. Putting tadedon modules into maven central repository seems the most important goal right now.

2009/11/30

XMind as eclipse plugin

About XMind

Have you tried XMind? It is very nice, open source mind mapping tool. If you have not tried mind mapping at all, maybe it is a good time to start as it helps a lot to visualize any conceptualization and then conceptualize some complex matters even better.

XMind is built on top of Eclipse RCP and so far has been distributed also as eclipse plugin. However now this option is no longer supported. As I spend a lot of time in eclipse it is much more convenient to me, to have mind maps and code in the same tool.

Installation

I found the solution. Here is the script install-as-eclipse-plugin.sh:

#/bin/bash -e

if [ ! $2 ]; then
 echo "Usage ./install-as-eclipse-plugin.sh xmind_path eclipse_path"
 exit 1
fi

XMIND_PATH="$1"
ECLIPSE_PATH="$2"

if [ ! -d $XMIND_PATH/plugins ]; then
 echo "Error - no /plugins directory in $XMIND_PATH - probably not XMind directory"
 exit 2
fi

if [ ! -d $ECLIPSE_PATH/plugins ]; then
 echo "Error - no /plugins directory in $ECLIPSE_PATH - probably not eclipse directory"
 exit 3
fi

echo "Copying XMind plugins from $XMIND_PATH to eclipse at $ECLIPSE_PATH"

# remove old xmind plugins (if they exist)
rm -fr $ECLIPSE_PATH/dropins/xmind
mkdir -p $ECLIPSE_PATH/dropins/xmind/plugins

# exclude language variants, and os specific stuff
PLUGINS=`ls $XMIND_PATH/plugins | grep -v nl_ | grep -v linux | grep -v win32 | grep -v macos`
for PLUGIN in $PLUGINS; do
 PLUGIN_NAME=`echo $PLUGIN | cut -d "_" -f 1`
 FOUND=`find "${ECLIPSE_PATH}/plugins" -name "${PLUGIN_NAME}_*"`
 if [ "$FOUND" == "" ]; then
  echo "Copying: $PLUGIN"
  cp -r $XMIND_PATH/plugins/$PLUGIN $ECLIPSE_PATH/dropins/xmind/plugins
 else
  echo "Plugin already installed: $PLUGIN_NAME"
 fi
done

This script will compare XMind plugins with plugins already available on eclipse installation and copy only these missing. It will also exclude all localization resources (I don't need them) and macosx stuff. Adjust these lines according to your needs.

All the plugins will be copied to dropins/xmind directory - it will ease the upgrade, if you want to remove xmind functionality from eclipse just remove this directory.

The only problem I have encountered so far is that on fresh eclipse installation, when new node is added to the map, there is exception from spell checker. Opening and closing xmind spell checking preferences in eclipse fixes this.

Update: I updated the script not to copy specific plugins, even if their version do not match. All the platform dependent stuff is excluded by default. The solution is tested with eclipse helios (3.6) and XMind 3.2.0.

How to use XMind in eclipse

Thanks to some comments I realized it could be not obvious how to use XMind inside eclipse. If you already have XMind file in one of your eclpse projects you can just click on it and it should open inside eclipse. Apparently you can also use File > Open File... from pull down menu to open any .xmind file. However you will not see all the Markers and Overview windows unless you open so called Mind Mapping perspective. You have only one default perspective in XMind, but several perspectives in default eclipse installation. Use Windows > Open Perspective > Other... > Mind Mapping from the pull down menu. You can also open separate windows specific to this perspective - just use Window > Show View. In order to create new XMind file, just open File > New File > Other... > Mind Mapping > Mind Map Workbook

2009/11/19

wondershaper is a real wonder

Have you ever experienced "slow internet" when there is another ongoing transfer on your wire which fully saturates the bandwidth. Even if one can accept high latency of HTTP transfers (sooner or later the page will appear in the browser), in case of interactive sessions like SSH it is completely unacceptable. Wondershaper is a great remedy with minimal side effects - especially if your are running your router on Linux machine.

Wondershaper is using CBQ instead of HTB and I am aware that there are better approaches to traffic shaping in Linux. But "traffic shaping" is usually associated with the context of splitting the bandwidth of single internet link among many hosts. This is too much in my case and wondershaper does exactly what I expect.

My ADSL line is 1024/256kb officially. But in logs I can see different values:

ATM dev 0: ADSL line is up (1312 kb/s down | 320 kb/s up)

At first I tried to provide these values to wondershaper, however they were too high (high latency still and packet drops in addition). By using different values I finally established that official numbers give the best trade-off between latency and link speed.

In case of my link the average download rate is around 126KB/s. Now with wondershaper it is around 120KB/s - about 95% of the original speed - this the cost. However SSH sessions work like a charm when updates are being downloaded and the browser loads pages almost as fast as usually.

Now specific section of my /etc/network/interfaces (Debian specific) looks like:

auto ppp0
iface ppp0 inet ppp
    pre-up /usr/local/sbin/firewall.sh start
    pre-up while ! grep 'Line up' /proc/net/atm/speedtch:0 &>/dev/null; do sleep 1; done
    post-up echo "1" >/proc/sys/net/ipv4/ip_forward
    post-up wondershaper ppp0 1024 250
    pre-down wondershaper clean ppp0
    pre-down echo "0" >/proc/sys/net/ipv4/ip_forward
    post-down /usr/local/sbin/firewall.sh stop

Update

With the 1024 256 values I still had some latency where my uplink was fully saturated. The 1024 250 values seems to work OK.

2009/11/07

smartd.conf: the ultimate settings

By "ultimate settings" I mean options which suit my needs best ;) . I had problems finding comprehensive example of smartd.conf options. Here is what I finally came to:

/dev/sda         \ # The device to monitor
 -a              \ # Implies all standard testing and reporting.
 -n standby,10,q \ # Don't spin up disk if it is currently spun down
                 \ #   unless it is 10th attempt in a row. 
                 \ #   Don't report unsuccessful attempts anyway.
 -o on           \ # Automatic offline tests (usually every 4 hours).
 -S on           \ # Attribute autosave (I don't really understand
                 \ #   what it is for. If you can explain it to me
                 \ #   please drop me a line.
 -R 194          \ # Show real temperature in the logs.
 -R 231          \ # The same as above.
 -I 194          \ # Ignore temperature attribute changes
 -W 3,50,50      \ # Notify if the temperature changes 3 degrees
                 \ #   comparing to the last check or if
                 \ #   the temperature exceeds 50 degrees.
 -s (S/../.././02|L/../../1/22) \ # short test: every day between 2-3am
                                \ # long test every Monday between 10pm-2am
                                \ # (Long test takes a lot of time
                                \ # and it should be finished before
                                \ # daily short test starts.
                                \ # At 3am every day this disk will be
                                \ # utilized heavily as a backup storage)
 -m root         \ # To whom we should send mails.
 -M exec /usr/share/smartmontools/smartd-runner # standard debian script

2009/11/05

dropbear: scp does not work, here is poor man's replacement

The dropbear project provides very interesting implementation of SSH server. It has advantage of very low memory footprint, which might be crucial in case of embedded devices. Personally I use dropbear on NSLU2 device (aka SLUG).

I was a little bit disappointed when I tried scp command against dropbear server (on debian host):

$ scp .ssh/id_rsa.pub root@slug:authorized_keys
bash: scp: command not found
lost connection

Another try:

sftp root@slug
Connecting to slug...
bash: /usr/lib/sftp-server: No such file or directory
Connection closed

Dropbear comes without scp and sftp-server commands. On debian you can find them in openssh-server package. Installing it would bring a lot of unwanted dependencies not even mentioning that I would have to make sure that OpenSSH server is not going to start and compete with my little dropbear. Here is simple scp-like solution.

cat .ssh/id_rsa.pub | ssh root@slug 'tee authorized_keys >/dev/null'

I hope it will help someone.

2009/06/27

Sparse image bundle for Time Machine backup

The command is:

$ hdiutil create -size 150g -fs HFS+J -nospotlight -imagekey sparse-band-size=131072 -volname “hostname-backup” /tmp/HOSTNAME_MACADDRESSWITHOUTCOLONS.sparsebundle
-size
the maximal size of the bundle in gigabytes (created image will be initially smaller though - about 250MB)
-fs HFS+J
the filesystem - using HFS is the main reason for preparing image anyway. TimeMachine depends on some HFS magic.
-nospotlight
prevents Mac OS from indexing this image
-imagekey sparse-band-size=131072
some sources on the Internet claim this is the best choice in terms of performance

When the image is ready, it should be moved to the network share where backup will be stored. Choosing the new location in TimeMachine preferences is the last step.

2009/03/15

gwt-servlet-war project, no more annoying gwt-servlet in the classpath

All the GWT libraries are available in the central maven repositories now. There are 4 different jars for single platform (gwt-user, gwt-dev, gwt-dev with platform classifier (thus there is even more jars the 4) and gwt-servlet.

If you are developing gwt application which will be packaged as war, these libraries should be included in pom.xml with something like this:

 <dependencies>
   <dependency>
     <groupId>com.google.gwt</groupId>
     <artifactId>gwt-user</artifactId>
     <version>${gwtVersion}</version>
     <scope>provided</scope>
   </dependency>
   <dependency>
     <groupId>com.google.gwt</groupId>
     <artifactId>gwt-dev</artifactId>
     <version>${gwtVersion}</version>
     <classifier>${platform}-libs</classifier>
     <type>zip</type>
     <scope>provided</scope>
   </dependency>
   <dependency>
     <groupId>com.google.gwt</groupId>
     <artifactId>gwt-dev</artifactId>
     <version>${gwtVersion}</version>
     <classifier>${platform}</classifier>
     <scope>provided</scope>
   </dependency>
   <dependency>
     <groupId>com.google.gwt</groupId>
     <artifactId>gwt-servlet</artifactId>
     <version>${gwtVersion}</version>
   </dependency>
 </dependencies>

GWT jars marked with provided will be available during development, but not packaged into war. This approach have only one drawback, core gwt classes are present in both - gwt-user, and gwt-servlet jar in the same time. In case of developing project in eclipse with m2eclipse plugin it leads to very annoying behavior (not finding sources, showing two candidate types with the same name, etc.).

I have created new gwt-servlet-war project to overcome this problem. The idea is very simple. Instead of the last gwt-servlet dependency from above example, one should put:

   <dependency>
     <groupId>pl.ncdc.gwt</groupId>
     <artifactId>gwt-servlet-war</artifactId>
     <version>${gwtVersion}</version>
     <type>war</type>
   </dependency>

After this change, war packaging will be supported by so called "war overlays" where wars specified as dependencies are merged into war being built.

And guess what gwt-servlet-war contains? Only gwt-servlet library in WEB-INF/lib. Thus project is in fact single pom.xml. Anyway It have to be packaged according to gwt versioning scheme.

If anyone have any idea how to set up maven repository on top of code.google.com's subversion, please contribute it to the project. Maybe I should promote this jar to be put in central maven repo, or rather suggest people responsible for putting gwt artifacts there to provide something of this kind along the line?

2009/02/03

Maven google code upload plugin

The project is located here.

Example setup (works well with my projects) looks like:

<plugin>
  <groupId>org.riedelcastro</groupId>
  <artifactId>maven-gcupload-plugin</artifactId>
  <version>1.0</version>
  <configuration>
    <uploads>
      <upload>
        <extensions>jar</extensions>
        <labels>Featured,Type-Archive,OpSys-All</labels>  
      </upload>
      <upload>
        <extensions>jar</extensions>
        <postfix>sources</postfix>
        <labels>Featured,Type-Source,OpSys-All</labels>
      </upload>
      <upload>
        <extensions>jar</extensions>
        <postfix>javadoc</postfix>
        <labels>Featured,Type-Docs,OpSys-All</labels>
      </upload>
    </uploads>
  </configuration>
</plugin>

The gcupload:gcupload maven target is added to our Hudson. We have differentia-javaica release build which takes care of everything - deploying jars to our Nexus as well as putting them to Google Code.

2009/02/02

Differentia Javaica

I started a new project called differentia-javaica. Here is the quote from the original description:

The aim of this project is to compare two java source codes and check if they are equal. It is not a simple diff. It uses ANTLR to construct two Abstract Source Trees for java types and eventually compare these trees. As a consequence white spaces and comments will not affect comparison. Reordering of elements in source code will be treated as difference though.

This kind of comparison is especially helpful when writing unit tests for java source code generators. When we have expected source code it is possible to check if it equals to generated source code.

We are writing some Java source code generators right now at NCDC and this tools is quite helpful in unit testing. Thus we want to share it with community.

2008/12/16

XML find and replace - xmlsed how to

Sed is a great tool when it comes to string replacement. With simple command like:

$ sed -i -e 's/log4j\.rootLogger=debug/log4j\.rootLogger=warn/' log4j.properties

, it will change appropriate value in log4j.properties file. It is especially useful in automatic scripts which customize configuration.

The problem I have encountered lately was connected with using sed for string replacement in xml files. I tried different regular expressions, and multi-line matching, and it was a real pain. I needed a kind of "xmlsed" in fact. Then I realized that even I don't know sed script syntax good enough, I know language which is tailored at manipulation of XML, which is XSLT. :)

For example when we have xml log4j configuration like this:

<?xml version="1.0" encoding="UTF-8" ?>
<!DOCTYPE log4j:configuration SYSTEM "log4j.dtd">
<log4j:configuration xmlns:log4j="http://jakarta.apache.org/log4j/">
  <appender name="console" class="org.apache.log4j.ConsoleAppender"> 
    <param name="Target" value="System.out"/>
    <layout class="org.apache.log4j.PatternLayout"> 
      <param name="ConversionPattern" value="%-5p %c{1} - %m%n"/> 
    </layout>
  </appender>

  <root>
    <priority value ="debug" />
    <appender-ref ref="console" />
  </root>
  
</log4j:configuration>
We have to prepare appropriate filtering xslt file:
<?xml version="1.0"?>
<xsl:stylesheet xmlns:xsl="http://www.w3.org/1999/XSL/Transform" version="1.0">

  <xsl:template match="root/priority/@value">
    <xsl:attribute name="value">warn</xsl:attribute>
  </xsl:template>

  <xsl:template match="@*|*">
    <xsl:copy>
      <xsl:apply-templates select="@*|node()"/>
    </xsl:copy>
  </xsl:template>

  <xsl:template match="comment()">
     <xsl:copy />
  </xsl:template>

</xsl:stylesheet>

, and then call:

$ xsltproc -o log4j.xml filter.xsl log4j.xml 

The XSLT file could look a bit verbose, but in fact only first template match is specific. The rest will just copy xml from input to output. Using this technique we can also strip some attributes or semantically replace more structured XML fragments. And all of this without removing XML comments.

The only drawback is that DOCTYPE will not be preserved.

If you want to match specific attribute value:

  <xsl:template match="Connector/@port[.='8080']">
    <xsl:attribute name="port">8180</xsl:attribute>
  </xsl:template>

2008/11/29

Nexus on debian

Nexus is very cool Maven Repository Manager, and debian is as cool server OS platform. I tried to match them. There was some pain, however finally I succeeded :).

Nexus is bundled as war now, thus the description is about installing it on tomcat.

In case of using debian etch (current stable), you may consider installing jdk 1.6 from backports. With jdk 1.6 you have to specify new JAVA_HOME=/usr/lib/jvm/java-6-sun in /etc/default/tomcat5.5.

Debian's tomcat has security manager turned on by default. Of course it could be easily disabled in /etc/default/tomcat5.5, however I feel safer when it is turned on :). Establishing security policy is not easy. My solution to the problem is based on work described in Mark Petrovic's article. I tweaked it a bit not to generate redundant rules. In case of nexus the resulting file looks as follows:

grant codeBase "file:${catalina.home}/bin/tomcat-juli.jar" {
    permission java.io.FilePermission "${catalina.base}/webapps/nexus/WEB-INF/classes/logging.properties", "read";
};

grant codeBase "file:${catalina.base}/webapps/nexus/WEB-INF/lib/-" {
    permission java.util.PropertyPermission "*", "read,write";
    permission java.io.FilePermission "/", "read";
    permission java.io.FilePermission "${catalina.base}/logs", "read";
    permission java.io.FilePermission "${catalina.base}/webapps/nexus/localhost/nexus/WEB-INF/plexus.properties", "read";
    permission java.io.FilePermission "${catalina.base}/webapps/nexus/localhost/nexus/WEB-INF/plexus.xml", "read";
    permission java.io.FilePermission "${catalina.base}/webapps/nexus/WEB-INF/log4j.properties", "read";
    permission java.io.FilePermission "${catalina.base}/temp", "read,write";
    permission java.io.FilePermission "${catalina.base}/temp/-", "read,write,delete";
    permission java.lang.RuntimePermission "defineClassInPackage.java.lang", "";
    permission java.lang.RuntimePermission "createClassLoader", "";
    permission java.lang.RuntimePermission "setContextClassLoader", "";
    permission java.lang.RuntimePermission "accessDeclaredMembers", "";
    permission java.lang.RuntimePermission "getenv.*", "";
    permission java.lang.RuntimePermission "accessClassInPackage.sun.misc", "";
    permission java.lang.RuntimePermission "accessClassInPackage.sun.reflect", "";
    permission java.lang.RuntimePermission "reflectionFactoryAccess", "";
    permission java.lang.RuntimePermission "getClassLoader", "";
    permission java.lang.RuntimePermission "modifyThread", "";
    permission java.io.FilePermission "${catalina.home}/sonatype-work", "read,write";
    permission java.io.FilePermission "${catalina.home}/sonatype-work/-", "read,write,delete";
    permission java.net.SocketPermission "*", "connect,resolve";
    permission java.lang.reflect.ReflectPermission "suppressAccessChecks", "";
    permission java.util.logging.LoggingPermission "control", "";
};

grant codeBase "file:${catalina.base}/webapps/nexus/WEB-INF/classes/-" {
    permission java.util.PropertyPermission "*", "read,write";
    permission java.io.FilePermission "${catalina.base}/webapps/nexus/localhost/nexus/WEB-INF/plexus.properties", "read";
    permission java.io.FilePermission "${catalina.base}/webapps/nexus/localhost/nexus/WEB-INF/plexus.xml", "read";
    permission java.io.FilePermission "${catalina.base}/webapps/nexus/WEB-INF/log4j.properties", "read";
    permission java.io.FilePermission "${catalina.home}/sonatype-work", "read,write";
    permission java.io.FilePermission "${catalina.home}/sonatype-work/-", "read,write,delete";
    permission java.lang.RuntimePermission "getenv.*", "";
    permission java.lang.RuntimePermission "defineClassInPackage.java.lang", "";
    permission java.lang.RuntimePermission "createClassLoader", "";
    permission java.lang.RuntimePermission "setContextClassLoader", "";
    permission java.lang.RuntimePermission "accessDeclaredMembers", "";
    permission java.lang.RuntimePermission "modifyThread", "";
    permission java.util.logging.LoggingPermission "control", "";
};

Copy these rules into 60nexus.policy file and place it in /etc/default/tomcat5.5. Restart of JVM is required to make these rules effective.

The line:

permission java.io.FilePermission "/", "read";

is redundant with other rules. The need of reading the whole filesystem seems to be a security flaw. I hope it will be eliminated in future nexus releases. I will fill the bug for this.

These security rules should work ok not only on debian, but also on any other system where tomcat is deployed. There are two system properties in use: catalina.home and catalina.base. This seems to be debian specific. In case of other systems catalina.home should be enough.

Nexus would create sonatype-work directory in user.home which is /usr/share/tomcat5.5 in case of debian. However with security manager we have to create it by ourselves.

host# mkdir /var/opt/sonatype-work
host# chown tomcat55:adm /var/opt/sonatype-work
host# ln -s /var/opt/sonatype-work /usr/share/tomcat5.5

The /var/opt/sonatype-work will become storage which should be backed up carefully when nexus is used not only as proxy, but also as local maven repository.

Now we can download the latest nexus from http://nexus.sonatype.org/using/download.html

Create logging.properties file with the following contents:

org.apache.juli.FileHandler.level = WARNING
java.util.logging.ConsoleHandler.level = WARNING

and put it into WEB-INF/classes inside the war.

Without this modification nexus would log every single HTTP request on console which would be redirected to catalina.out log file. To much verbose default logging seems to be another nexus bug.

Strip the version number from war file, stop tomcat with:

host# /etc/init.d/tomcat5.5 stop

Put nexus.war in /var/lib/tomcat5.5/webapps.

host# /etc/init.d/tomcat5.5 start

Nexus should be visible at http://debianhost:8180/nexus/

Upgradges should be as easy as putting new nexus war in webapps.

2008/06/26

Maven Integration for Eclipse and ClassNotFound exception

I have been using Maven Integration for Eclipse plugin for some time and I am very fond of it. It is awesome. I imagine there is no a single solution to the problem of bridging two java project meta-descriptors - maven's represented by pom.xml and eclipse's represented by artifacts like .classpath and .project. The way it is implemented in this plugin is just awesome.

There was only one problem I have encountered while using m2eclipse plugin. After upgrade to 0.9.4 release, my eclipse-maven projects stopped working with ClassNotFound exception when being run from eclipse as whether Applications or JUnit tests. It was caused by a change introduced in default eclipse output folders for maven projects. It use to be target-eclipse/classes and is target/classes now - just like standard maven output directory. There is a rationale behind this change.

In order to fix the problem just select a project and choose Maven > Update Project Configuration from context menu. I've spent some time trying to understand what is going on - probably some kind of warning should be shown in case of projects with legacy paths. I hope this entry could help someone having similar problem.

m2eclipse plugin is on a good way to become a project under eclipse umbrella, great.

2008/06/18

Eclipse Ganymede - rejoicing in virility

Origins of the meme

The phrase "rejoicing in virility" is translated etymology of term ganymede. Ganymedes was the most handsome among mortals - a mythical hero of ancient Greek cluture.
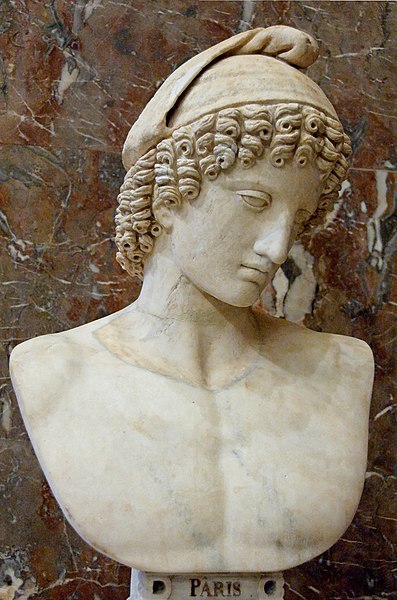
Term ganymede is associated with some memes - probably quite selfish ones. As long as they are referred in this post and as they are understood by readers of this post I assume the last statement being proved. :) In evolution of culture some old memes die, some other are born, some other gain a new life.

Memes of ancient Greek culture often influence birth of new memes and then persist somehow within new ideas. Soon after Galileo discovered moons of Jupiter, one of them was named Ganymede.

A new meme associated with term Ganymede has been born recently. I suppose it's life will be relatively short (about year), although very intensive. For sure it will cause creation of new memes.

If I was asked some time ago what eclipse is, I would not have much problem with the answer - another Java IDE. Now eclipse is much more. We can call it a platform for hosting different development components. Every day connotations of the term eclipse grow like branches of a big tree.

As eclipse is astronomical term, the ganymede used for naming software follows this convention. If I was asked what this Ganymede is I would say: it is an attempt to steer some specific evolutionary process associated with software development. An attempt to stop this evolution for a while. An attempt to match different software projects in the shape they interoperate the best. There is a reason the platform is called ecosystem.

It is not the first time that Eclipse Foundation freezes the evolution at some specific stage. It is called "simultaneous releases" and so far we had two previous releases of this kind also named after moons of Jupiter - Calisto and Europa.

This introduction was long and boring. :) What really interest me as [not-so-]pragmatic programmer, and probably interests you who is reading this post right now, is a comparison between Ganymede and Europa.

Downloading

Ganymede could be downloaded from a new site. What is nice here - special link for downloading Linux AMD64 version. Finding proper version for this platform was a pain in the past. I have downloaded Mac OS X version numbered as RC3.

Launching

I have checked that the Mac OS X version comes with eclipse.ini file adjusted for more realistic usage scenario

-Xms40m
-Xmx512m
-XX:MaxPermSize=256m

Good, I won't have to tweak it by hand. It was probably fixed also in the latest Europa bundles, but for sure not in the initial ones.

During eclipse start I spotted new splash screen, quite interesting to see what else could be arranged with the same conceptual graphical elements and the same color scheme.

My workspace seems to be upgraded quite smoothly. From the first sight I cannot see anything new in eclipse appearance. Although generally being liberal I tend to be conservative on some topics. One of them is look and behavior of tools I am using and I got use to. It is not about software only. It could be about hammer or screwdriver, any extension of human body or human mind. :)

Installing plugins

Although version Eclipse IDE for Java EE Developers provides quite comprehensive development environment there are still some missing futures I use on day to day basis.

Installation of eclipse plugins has been completely redesigned. Now it is simpler and clearer and works without much ambiguity as it use to be. New option of Automatic Updates was added to general eclipse preferences, nice. However there seems to be some software update related bug in RC3, eclipse is trying to install the same upgrades forever. Fortunately when I came back to eclipse.org there was RC4 release available which upgrades without any problem.

I see only one drawback comparing to previous Software Updates functionality. Selecting plugin to install will not show brief description. The description could be find in General Information after right clicking and choosing Properties.

Ganymede comes with dozens of new features comparing to Europa. Some of them I have been using already however specifying Update Site manually. Now these releases are synchronized available from predefined sources. I will just name things important to me:

  • Remot System Explorer (included by default in Java EE bundle)
  • SVN Team Provider
  • Usage Data Collector (included by default)

The last feature is quite interesting:

The Usage Data Collector collects information about how individuals are using the Eclipse platform. This information is periodically uploaded to servers hosted by The Eclipse Foundation (though this is configurable). The intent is to use this data to help committers and organizations better understand how developers are using Eclipse.

Target Users of the Data:

  • Users of Eclipse
  • Committers working on Eclipse projects
  • ISVs and organization creating Eclipse based software
  • Enterprise IT departments that make extensive use of Eclipse Foundation
  • Academic researchers that want to study how developer work Data to Be Collected

Captured data is associated with a user through a combination of workstation and workspace ids that are automatically generated by the collector. This identification is not tied to any personal information about the user.

The usage data monitors:

  • Start up and shutdown times of a workspace
  • What is being used and when (timestamp), including
    1. Loaded bundles
    2. Commands accessed via keyboard shortcuts
    3. Actions invoked via menus or toolbars
    4. Perspective changes
    5. View usage
    6. Editor usage

Where possible, the usage data collector also capture the symbolic name and version of the bundle contributing the command/action/perspective/view/editor.

This functionality reminds me Debian Popularity Contents. Did I say something about evolution. It is definitely a kind of convergence.

Subversive plugin is now part of the distribution. Unfortunately it still depends on connectors provided by Polarion. I added:

http://www.polarion.org/projects/subversive/download/eclipse/2.0/update-site/

to my Update Sites, nice feature here (or rather lack of annoyance :) ) - I am not longer forced to provide Site Name - just URL.

I installed SVNKit 1.1.7.

Now it is a time for Maven Integration Plugin plugin, I installed:

  • Maven Integration for Eclipse
  • Maven POM XML Editor
  • Maven: The Definitive Guide book

BTW there is a proposal to create Eclipse Integration for Apache Maven (IAM) under the umbrella of the Eclipse Foundation, great.

I installed additional plugins without any problem:

And now a little bit about new features I can see from the first sight:

New features and other remarks

Unfortunately the most annoying bug (at least for Mac OS X users) of the latest Europa updates remains in Ganymede (I suppose it is connected with SWT). :(

I can see italics text in case of attributes shown in XML editor, interesting.

While browsing available views and perspectives I spotted some interesting things I hadn't tried.

  • Palette - I suppose it is available to support diagram editin
  • Snippets - something new
  • Templates - looks like new interface to the old functionality
  • TCP/IP Monitor - it is from Debug Perspective, great I hope it will replace external sniffer for debugging networking code
  • JPA related views
  • Execution Plan in SQL Development perspective

That's all for now. I hope to write more when I will start using these new features. So far ganymede looks very promising and interesting.

Conclusion

Valueable memes never die. :) Eclipse Foundation is quite good in spreading own memes. It is very interesting to see what kind of "social engineering" is used in order to attract mass attention for products of open source movement . Firefox is a perfect example with todays Download Day 2008.

2008/06/12

Building GWT module library in maven

GWT module library should be prepared according to specific convention. The part of module source code which is compiled from Java into Java Script, resides in org.foo.module.client package by default. GWT compiler will use Java sources, not compiled Java bytecode, thus it is important to include "client side" sources inside module library jar file. Building proper jar requires some modification to project's standard pom.xml file:

<resources>
  <resource>
    <directory>src/main/java</directory>
      <includes>
        <include>**/client/**</include>
        <include>**/public/**</include>
        <include>**/*.gwt.xml</include>
      </includes>
    </resource>
</resources>

2008/06/07

Sharing GWT project

The Google Web Toolkit distribution comes with very handy tools for seeding new projects. The drawback of this utility is that produced project stub will reference local GWT distribution directory. In case of homogenous development environment like every developer using windows machine, some common convention of keeping GWT distribution on C:\gwt-windows-x.y.z could be introduced. There is still problem when new GWT is released, because path to GWT home is hardcoded in project configuration.

I want to propose a solution based on some eclipse configuration, which will not only ease GWT upgrades, but also allows developers working on different operating systems to share GWT projects. Here is a quick how to:

In eclipse preferences add Classpath Variable named GWT_HOME, and point it to your GWT distribution directory.

Run GWT project creation scripts as usual:

$ projectCreator -eclipse foo-project
$ applicationCreator -eclipse foo-project org.foo.client.FooApp

Edit .classpath and replace:

<classpathentry kind="lib" path="/foo/bar/gwt-mac-x.y.z/gwt-user.jar"/>

with:

<classpathentry kind="var" path="GWT_HOME/gwt-user.jar"/>

Now in eclipse:

  • choose Open Run Dialog
  • select FooApp Java Application
  • go to Classpath tab
  • from User Entries remove reference to gwt-dev-platform.jar
  • click Advanced...
  • choose Add Classpath Variables
  • select GWT_HOME and Extend... to gwt-dev-platform.jar

The FooApp launch configuration should work now. However as you can see it is still platform dependent. To overcome this just duplicate FooApp Java Application twice in Run Dialog, every time renaming it according to destination platform. It should be something like:

  • FooApp-win
  • FooApp-linux
  • FooApp-mac

Each of above launch configurations should have GWT_HOME/gwt-dev-platform.jar in User Entries where platform should be set according to launch configuration suffix.

That's all. You can share the project in your source code repository and enjoy abstract configuration which is not limited to your environment.

Just remember to add -XstartOnFirstThread VM argument in case of mac launch configuration.

2008/04/08

Time Machine backups on SMB share

Finally I managed to perform network Time Machine backups.

Despite the fact that network Time Machine backups were advertised by Apple before Leopard launch, this functionality has been disabled just before the release. I don't want to speculate about true reasons behind this move. There are some rumors that it was because of new apple's Time Capsule product and an attempt to bind network backups of Mac OS X to this device. Could be partially, however problem seems to be technical, not economical.

Network TM backups are disabled by default, however turning this feature on is quite simple, it is enough to run in Terminal:

defaults write com.apple.systempreferences TMShowUnsupportedNetworkVolumes 1

In my case one more required step was to create sparse image bundle for the backup named in pattern

hostname_mac address without separators

, on the destination backup share.

(Update: you might be interested in precise command for creating sparse image bundle.)

This kind of backup use to be potentially unstable - there is an apple forum post regarding this issue. The problem seems to be fixed now with the latest TimeMachine and AirPort update. Probably this bug was an original rationale behind disabling network TM backups when the Leopard was released. Are there any more obstacles for network TM backups? If not - apple, please make network volumes appear in TM's drive chooser by default. Also the need of preparing sparse image bundle in order to make a backup seems to be too difficult for many Mac OS X users. Is it made for purpose? I believe there is still some technical issue behind. The only thing that worries me is backup instability. :(

2008/03/26

Gimp, XQuartz, Gtk+ for Mac OS X and OpenOffice Aqua on Leopard

I wanted to have gimp on my mac. As it was suggested on the Wilber loves apple site, I also installed XQuartz - X11.app improved comparing to version shipped with leopard. It works fine. With this little hack I was even able to get rid of the most annoying feature of some X11 apps running on Mac. :)

While browsing WLA forum I found information, that there is native OS X gtk port which allows to build almost fully useable gimp - very interesting.

Unfortunately after X11.app upgrade OpenOffice stopped working. :( It is still possible to run it with console, but not from the icon. Looking for the solution I found more interesting OS X resources:

2008/02/19

JIRA with security manager

We have tried many issue/bug tracking systems so far: scarab, mantis, bugzilla, trac, just to name a few. Personally I really like the last one with very nice wiki syntax, and a lot of plugins. Trac would be my issue tracker of choice for open source projects, however for the company like NCDC it is not sufficient. This is the reason why we bought JIRA.

JIRA deploys quite nicely in many different containers. Unfortunately not in standard debian's tomcat which has security manager turned on. We spent some time trying to figure out which permissions are required. I thought being very smart performing remote debugging of tomcat instance with JIRA deployed. I just set breakpoints in all the constructors of SecurityException. :)

Eventually I came across java.security.debug property. :)

There is appropriate issue on JIRA's JIRA :) I posted our established solution policy file in this ticket. I hope it will be covered by documentation one day.

I discovered another issue after messing with configuration a little bit more.